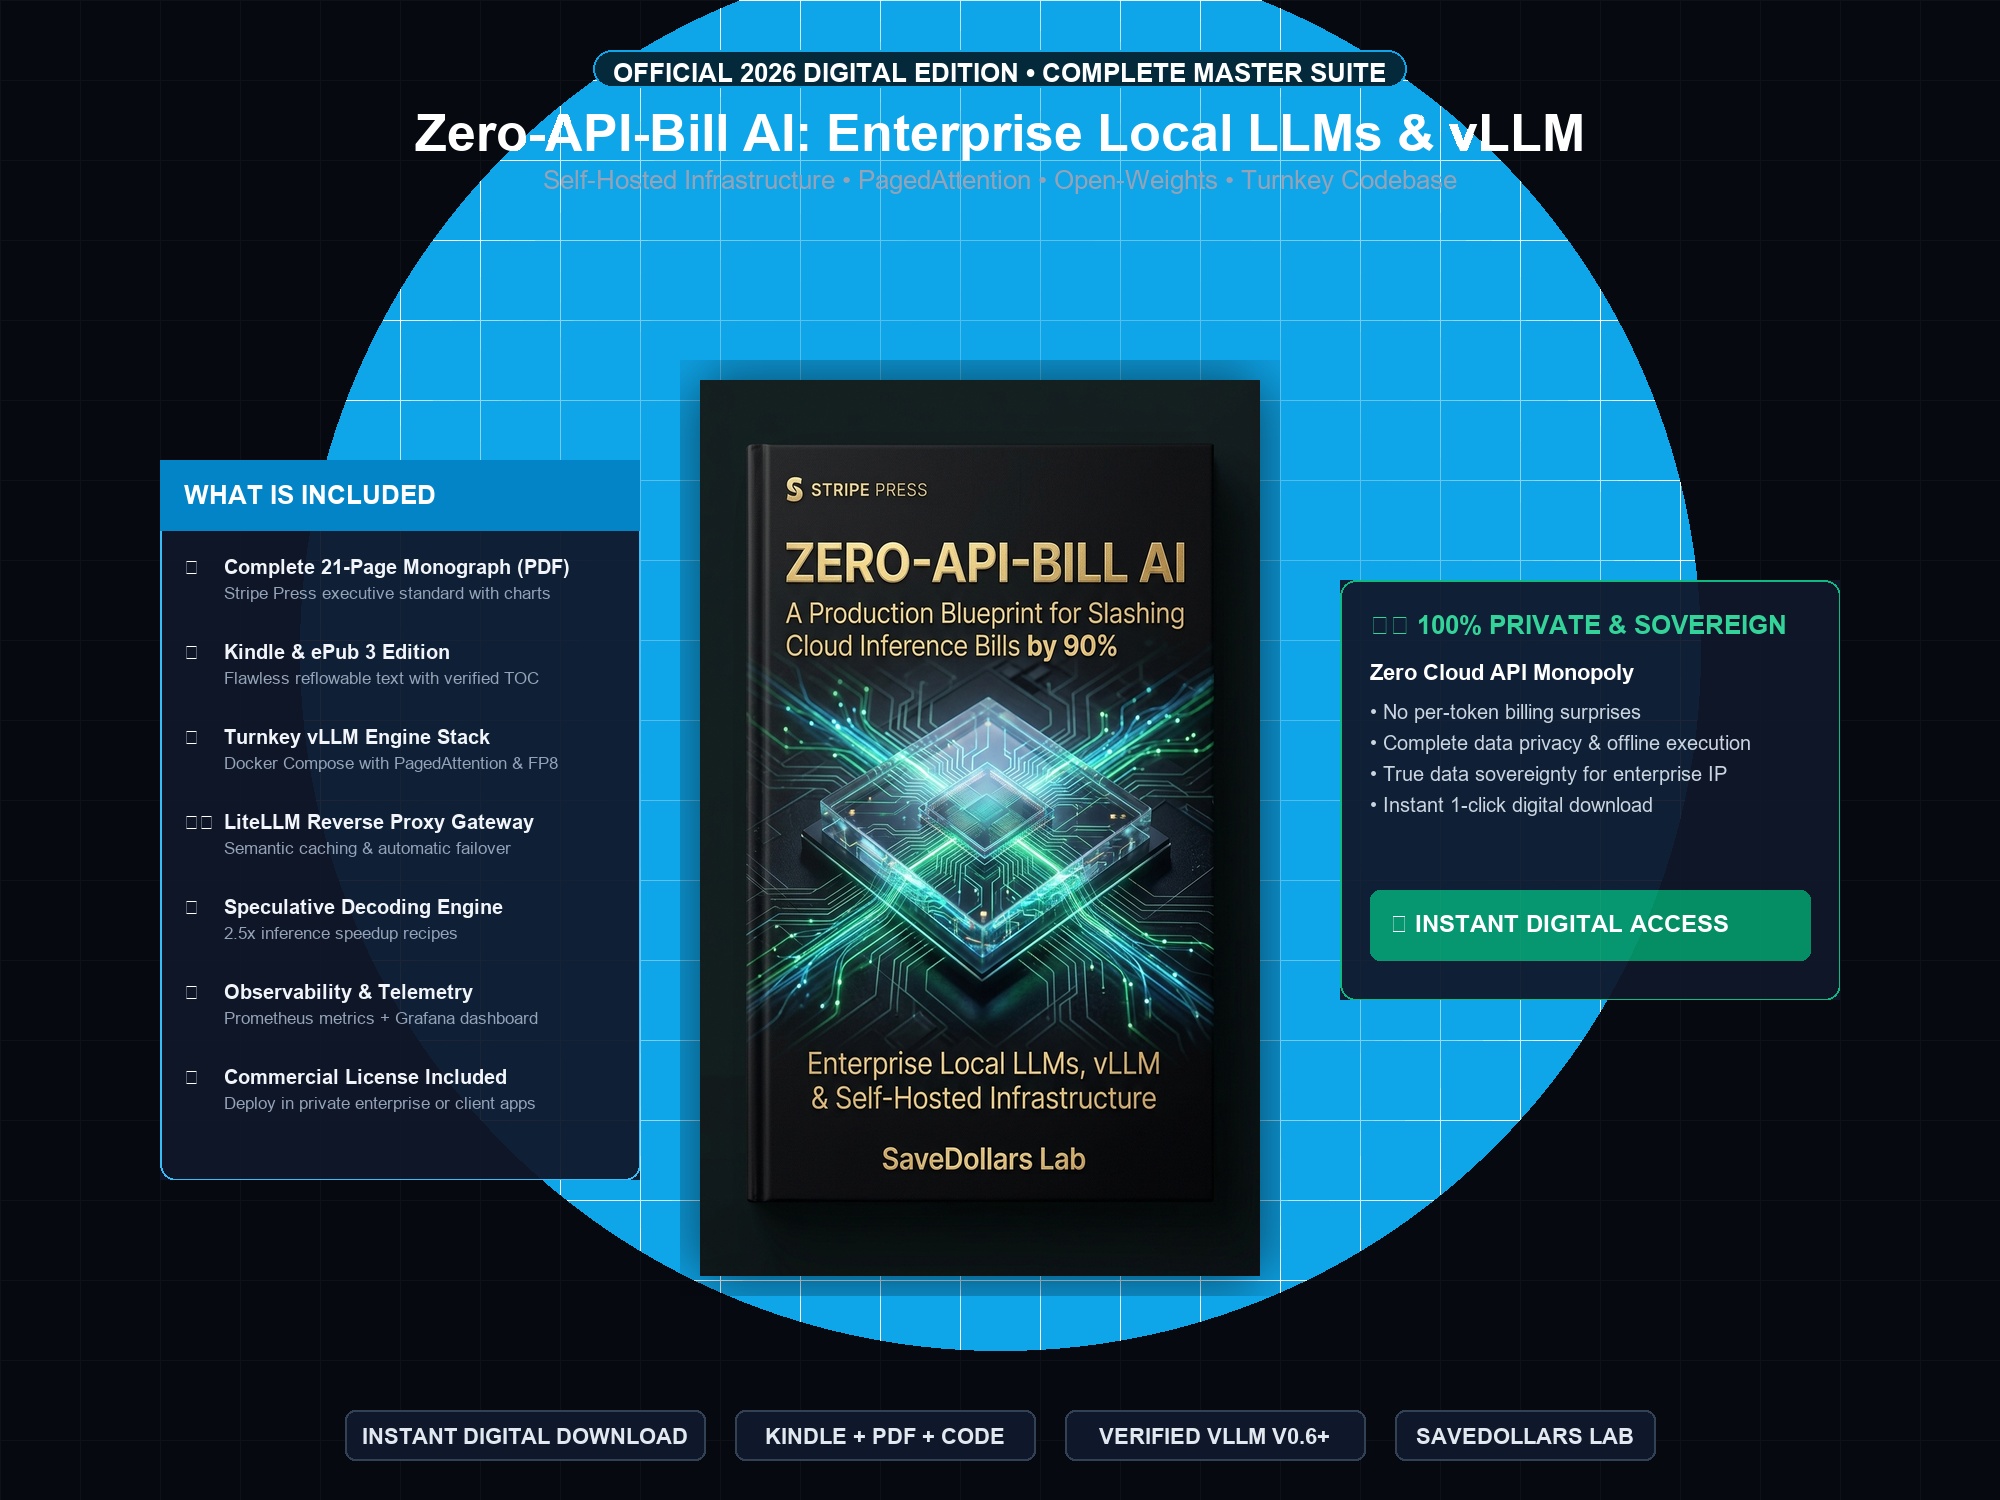
Zero-API-Bill AI: Enterprise Local LLMs & vLLM Master Suite
Stop paying cloud rent on every agent reasoning step. Deploy sovereign, self-hosted LLM infrastructure delivering 1,400+ tokens/sec at $0.00 marginal cost.
💻 Complete Docker & Python Repo
⚡ Instant Digital Delivery
4 Technical Pillars Covered Inside
1. The Token Cost Crisis
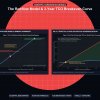
Multi-agent token compounding economics, memory bandwidth physics, the Roofline Model, and why dedicated silicon breaks even in ~45 days.
2. vLLM & PagedAttention
Virtual memory paging applied to KV caches. Eradicate internal and external fragmentation to scale multi-tenant concurrency up to 24x.
3. Quantization & Draft Models
AWQ 4-bit weight compression, FP8 precision preservation, and speculative decoding recipes pairing draft models for 2.5x speedups.
4. High-Availability AI Gateways
LiteLLM OpenAI-compatible reverse proxies, Redis semantic caching, Prometheus metrics, and Grafana telemetry for enterprise SLAs.
📦 Complete Turnkey Codebase Repository (Inside ZIP):
- 📁 Zero_API_Bill_AI_Enterprise_Local_LLMs.epub — Reflowable e-reader book
- 📁 Zero_API_Bill_AI_Enterprise_Local_LLMs.pdf — 21-page 7×10 Stripe Press standard monograph
- 📁 production-codebase/docker-compose.vllm.yml — Production vLLM engine stack
- 📁 production-codebase/docker-compose.litellm.yml — Reverse proxy & semantic cache stack
- 📁 production-codebase/benchmark_vllm.py — Async concurrency & throughput benchmark
- 📁 production-codebase/litellm-config.yaml — Router settings & fallback rules
- 📁 production-codebase/requirements.txt — Turnkey dependencies
100% Data Sovereignty & Commercial License
Full lifetime license to deploy and customize across personal and enterprise infrastructure. Zero recurring cloud fees.